Real-world demonstration data, built around your requirements.
Describe the activities, scenarios, perspectives, volume, and labels your model needs. We design and operate the collection program, capture and synchronize the data, run privacy and quality review, annotate every approved episode, and deliver a versioned dataset. Already have videos? We annotate those too.
Two Ways to Start
Use your data, or commission a new collection.
The same project-specific annotation and quality workflow supports both existing source data and newly produced demonstrations.
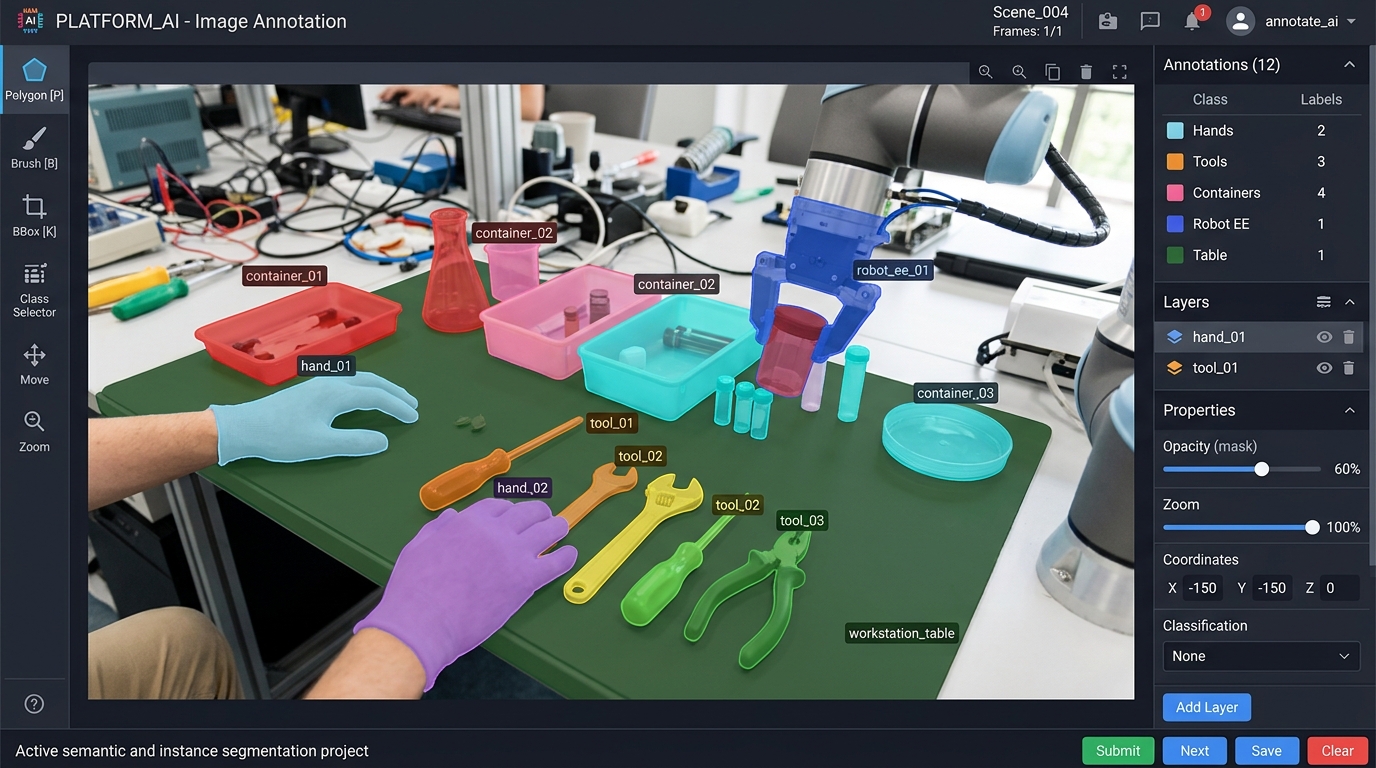
01 // Existing Data
Send us your robotics or demonstration videos.
We can segment, annotate, validate, correct, convert, and enrich supplied videos, images, sensor data, point clouds, or existing labels according to your ontology.
View annotation services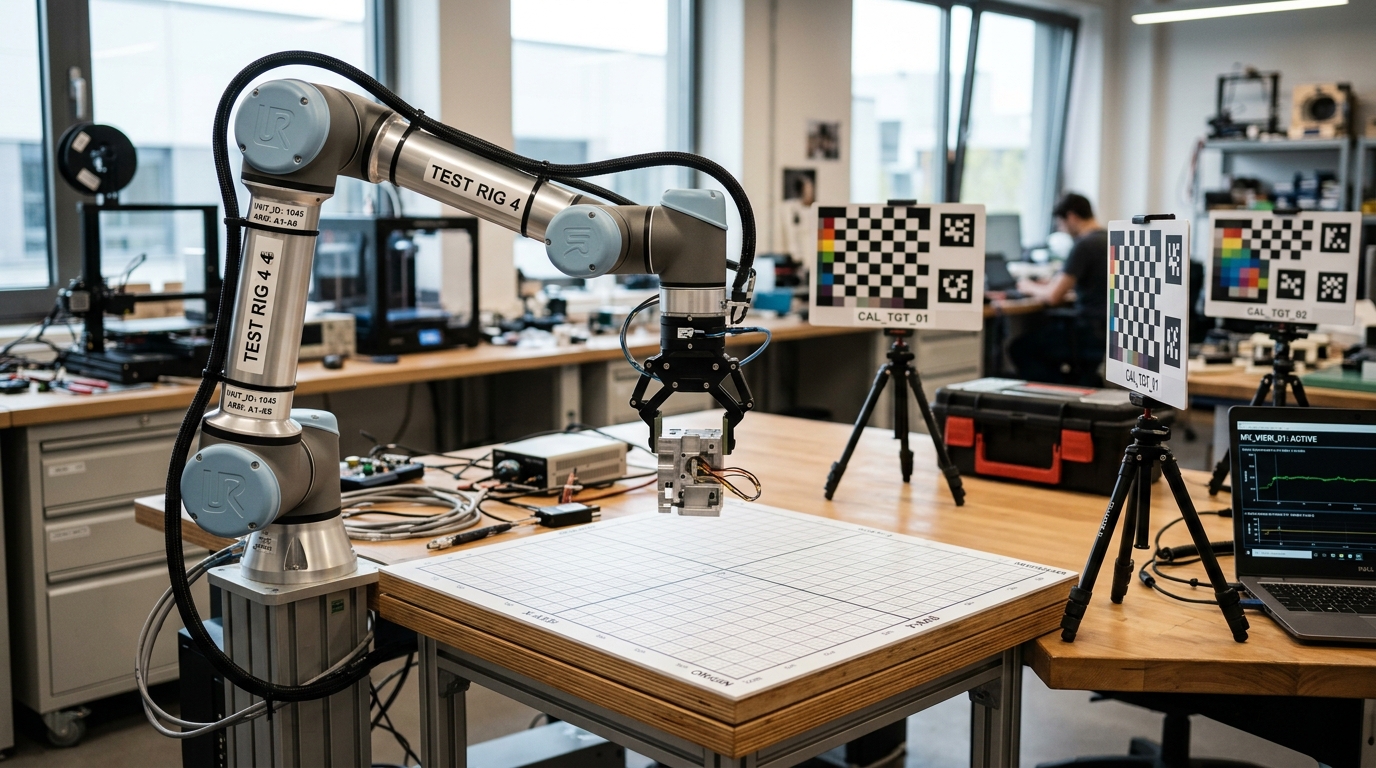
02 // New Data Production
No source data yet? Define what should be recorded.
We turn task requirements into a production protocol, organize real-world demonstrations through controlled collection operations, review and synchronize the recordings, annotate them, and prepare the final dataset.
Request a collection pilotCollection Scale
Built for pilots and high-volume production.
From focused pilot datasets to large-scale, multi-environment collection programs. Scale across tasks, participants, environments, viewpoints, sensor configurations, and annotation depths.
Program Tier 01
100+ hours
Task-specific demonstrations with project-defined collection, QA, annotation, and delivery controls.
Program Tier 02
1,000+ hours
Task-specific demonstrations with project-defined collection, QA, annotation, and delivery controls.
Program Tier 03
10,000+ hours
Task-specific demonstrations with project-defined collection, QA, annotation, and delivery controls.
Program Tier 04
Custom enterprise scale
Task-specific demonstrations with project-defined collection, QA, annotation, and delivery controls.
Annotyx AI designs the collection protocol, contributor workflow, quality gates, annotation schema, capacity plan, and delivery pipeline around the required production volume.
Model Capabilities
Training inputs for physical representation learning.
How custom demonstrations support key perceptual and control models.
VLA-Model Pretraining
Diverse demonstration segments to pretrain Vision-Language-Action policies for task understanding.
Hand-Object Interactions
High-resolution multi-angle logs to model contact points, grasp frames, and finger positioning.
Success & Failure Classification
Explicit recordings of failed task trajectories and recovery loops to train robust world models.
Affordance Learning
Mapping dynamic object surfaces and spatial boundaries to pre-determine potential actions.
Task Decomposition
Breaking complex, multi-stage sequences into clean temporal subtasks labeled sequentially.
Action Anticipation
Predicting next-step action verbs and object targets based on sequential visual histories.
Multiview Perception
Aligning camera feeds from wearable chest setups and workspace mounts to resolve occlusion.
Human-to-Robot Transfer
Gathering structured human kinematics that map cleanly onto target robotic joint configurations.
Operating Lifecycle
From requirements to a validated dataset.
One controlled workflow covers both customer-supplied source data and newly produced demonstration recordings.
Define Requirements
We scope tasks, environments, people, perspectives, volume, variations, annotation depth, output format, and model objectives.
Design the Pilot
Capture instructions, task definitions, annotation guidelines, and acceptance criteria are validated in a focused pilot before production scaling.
Collect or Ingest
We ingest existing customer videos or operate new recording programs around the approved collection protocol.
Label the Data
Tasks, subtasks, actions, objects, states, interactions, outcomes, and temporal boundaries are labeled to the agreed ontology.
Review Quality
Raw files and labels are checked for completeness, consistency, technical usability, privacy requirements, and schema validity.
Package the Dataset
Videos, annotations, metadata, and documentation are delivered in the agreed standard or project-specific format.
Robotics Annotation
Labels for tasks, interactions, states, and outcomes.
Annotation depth is defined per project rather than forced into a fixed schema.
Tasks & Time
- Task and subtask labels
- Frame-accurate action segments
- Instruction-to-action alignment
- Detailed video captions
Hands & Objects
- Active hand and object
- Grasp and release points
- Contact and collision events
- Pick-and-place interactions
State & Outcome
- Object state transitions
- Success and failure labels
- Failure-mode explanations
- Recovery attempts and actions
Space & Motion
- Body and hand keypoints
- Object positions and trajectories
- Movement directions
- End-effector or arm poses when available
A typical manipulation sequence can be labeled as: detect object → determine grasp point → approach → grasp → move → reach target → release → evaluate outcome.
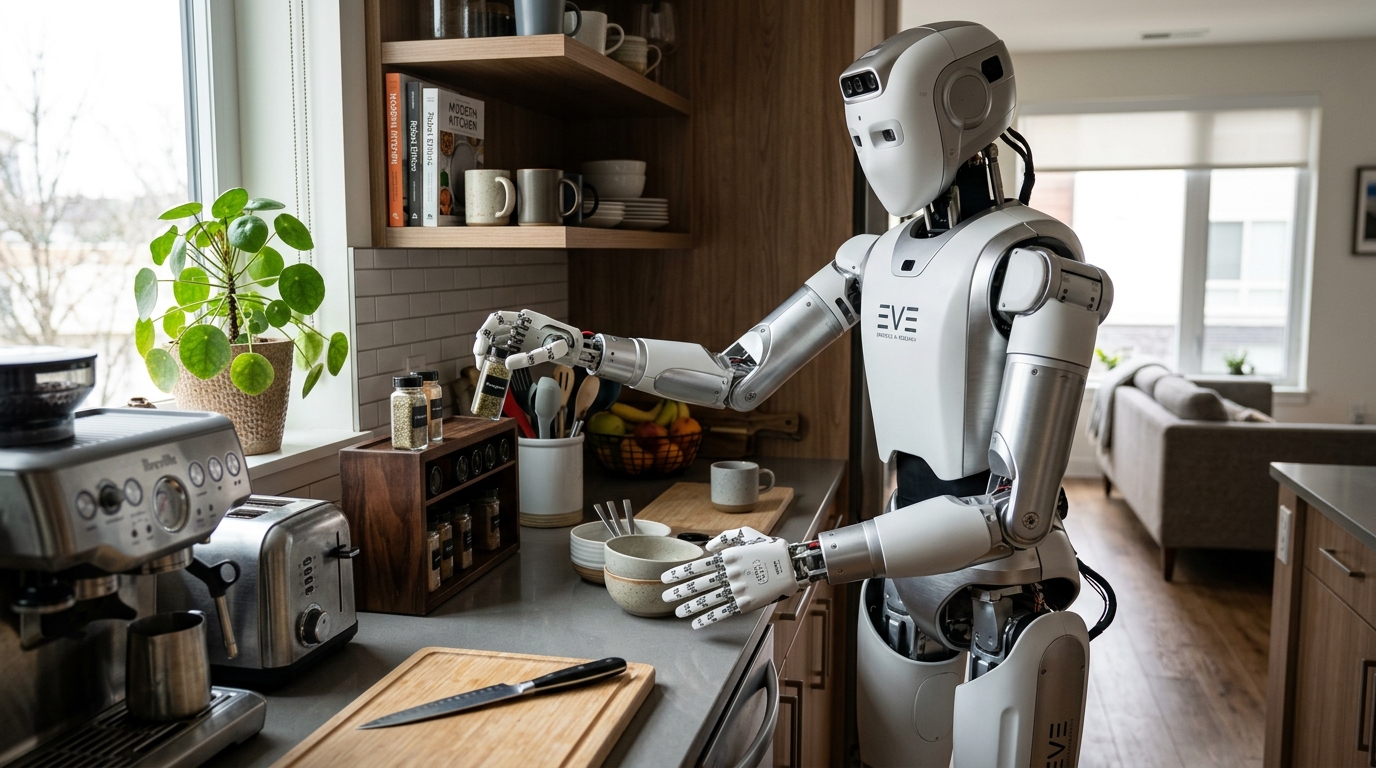
Multiview kitchen demonstrations for robotics models.
Project-specific kitchen collections capture defined human demonstrations across required tasks, hours, camera views, participants, environments, objects, variations, labels, and delivery formats.
Example Task Set
- Sort ingredients and objects
- Pick up, move, and place items
- Open and close drawers or cabinets
- Load and unload dishes
- Clean worktops or tables
- Pour liquids and open packaging
- Use simple tools or appliances
- Complete multi-step kitchen routines
Capture variations can include different people, handedness, speeds, object positions, lighting, task order, successful attempts, failures, retries, ego views, third-person views, and synchronized cameras.
Designed for multimodal robotics training pipelines.
Human demonstration datasets support visual representation learning, task understanding, temporal planning, affordance learning, world modeling, and human-to-robot transfer. The delivered schema can also align with robot-specific telemetry supplied by the customer.
Suitable for
- Pretraining visual-language representation models.
- Modeling temporal subtask planning & workflows.
- Isolating success and failure markers.
- Learning affordance bounds and scene configurations.
Integrated when supplied
- Proprioceptive joint positions or motor actions.
- End-effector commands or force torque metrics.
- Gripper force values or tactile signals.
- Direct executable robot policies.
Technical note: Direct robot-control programs often combine demonstration video with robot-specific state and action data. Annotyx AI structures the visual, temporal, semantic, and metadata layers for that broader training stack.
Need existing videos labeled or a new dataset produced?
Describe the activities, data volume, perspectives, variations, annotations, and target format. We will design a controlled pilot and the path to production-scale delivery.